Overview
New Project Wizard
Export Wizard
Settings
Purchase and Support
Settings
You can open the Settings window by clicking Tools->Settingsor by pressing Alt+F7. This window allows you to change the following settings:
General Tab
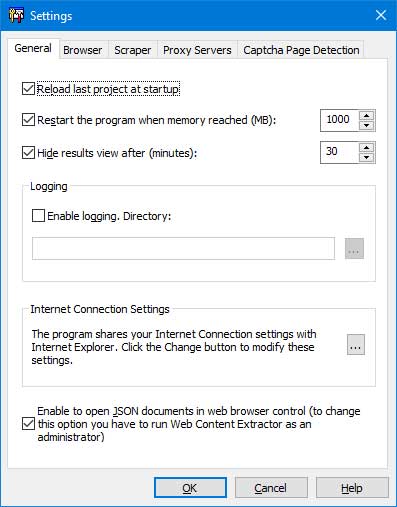
Reload last project at startup - if this option is enabled, the program will automatically open the last project when you start the program.
Restart the program when memory reached - if this option is enabled and memory reached the limit, then it will be restarted automatically to release the memory.
Hide the results view after - if this option is enabled, then the program will hide the results view after x minutes.
Enable logging - enable this option if you want to log web scraper events. The logging directory is the directory where the Web Content Extarctor stores log files, the default logging directory is a current directory.
Internet Connection Settings - the program uses the system Internet connection settings. You can change these settings by clicking the "..." button.
Enable to open JSON documents in Internet Explorer browser - to change this option you have to run Web Content Extractor as an administrator.
Browser Tab
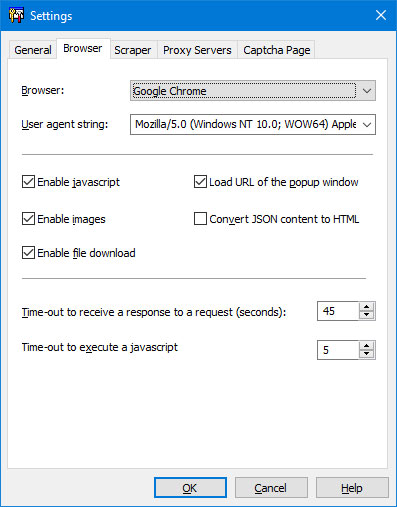
Browser:
- Google Chrome - the program will use Google Chrome to download webpages.
- Internet Explorer - the program will use Internet Explorer to download webpages.
- HTTP downloader - the program will download webpages via simple HTTP requests.
User Agent String - the string attached to the request header (if you use Google Chrome you need to restart the program to have this change take effect). This is a global setting and applies to all projects.
Enable javascript - enable this option if you want to allow scripts in the web browser.
Enable images - enable this option if you want to see images in the web browser.
Enable file download - This option enables the browser to download files.
Delay between download and parsing data - the delay that is necessary to execute all scripts on a page.
Time-out to receive a response to a request - the maximum time the program will wait for a response from the server after requesting a page.
Time-out to execute a javascript - the maximum time the program will wait to execute a javascript.
Scraper Tab
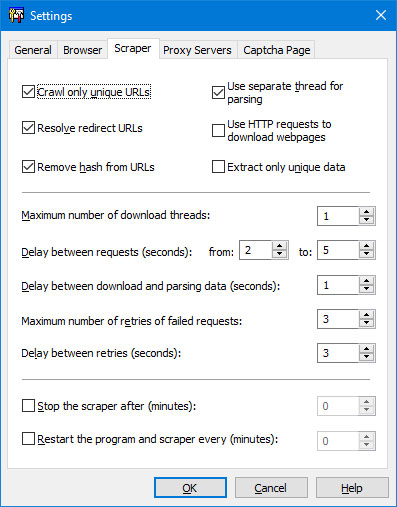
Crawl only unique URLs - if this option is enabled, the program will add only new links to the project, i.e. URLs that are not in the scraper URL list yet.
Extract only unique data - if this option is enabled, the program will add only new data to the project, i.e. data that are not in the database yet.
Disable images in browser - if this option is enabled, the program will not download images when loading webpages.
Resolve redirect URLs - if this option is enabled, the program will update the URLs of redirected links.
Remove hash from URLs - if this option is enabled, the program will remove hash string from the URLs. A hash string is the part of the URL that appears after the '#' sign.
Maximum number of download threads - the number of simultaneous connections to a server.
Delay between requests - the delay necessary to prevent the server from being overloaded by multiple requests from the program. We recommend that you set the delay to at least 1-2 seconds.
Maximum number of retries of failed requests - the maximum number of retry attempts after a request fails.
Delay between retries - the pause the program takes before trying again after a failed request.
Stop the scraper after - limits the crawling time. Set the number of minutes a project is allowed to run. If this is reached, the program stops the project. If set to zero, no time limit is imposed.
Restart the program and scraper - Set the number of minutes to restart the program automatically.
Captcha Page
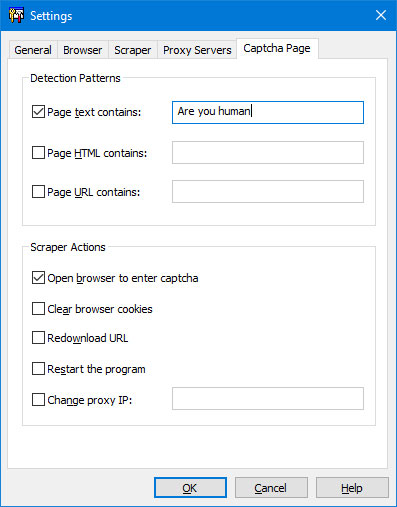
You can specify page patterns to identify captcha pages. When the program detects a page matching this pattern, it automatically pauses the extraction process and performs the actions you defined. You can define the following types of detection patterns:
- Page text contains - the program will scan the page text for the specified text.
- Page HTML contains - the program will scan the page HTML for the specified text.
- Page URL contains - the program will scan the page URL for the specified text.
You can define the following actions:
- Open browser window and execute the captcha page actions.
- Open browser window and navigate to the URL.
- Clear browser cookies.
- Redownload URL.
- Restart the program.
Proxy Servers Tab
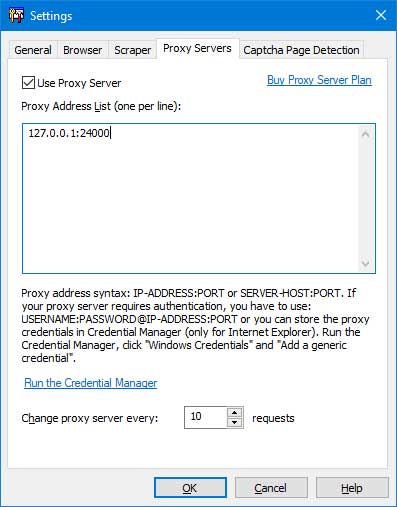
Use Proxy Server - if this option is enabled, the program will use proxy server to internet connection. Use the following syntax for the proxy address: <ip_address>:<port> where <ip_address> is the Ip address of the proxy server, and <port> is the port number that is assigned to the proxy server. If your proxy server requires authentication, you have to use: <username>:<password>@<ip_address>:<port>
Change browser proxy every x requests - the program will change the browser proxy every x requests.